AI Triage for Enterprise IT Service Tickets
A practical boundary for using AI to classify, enrich, prioritize, and route IT tickets before a specialist takes ownership.
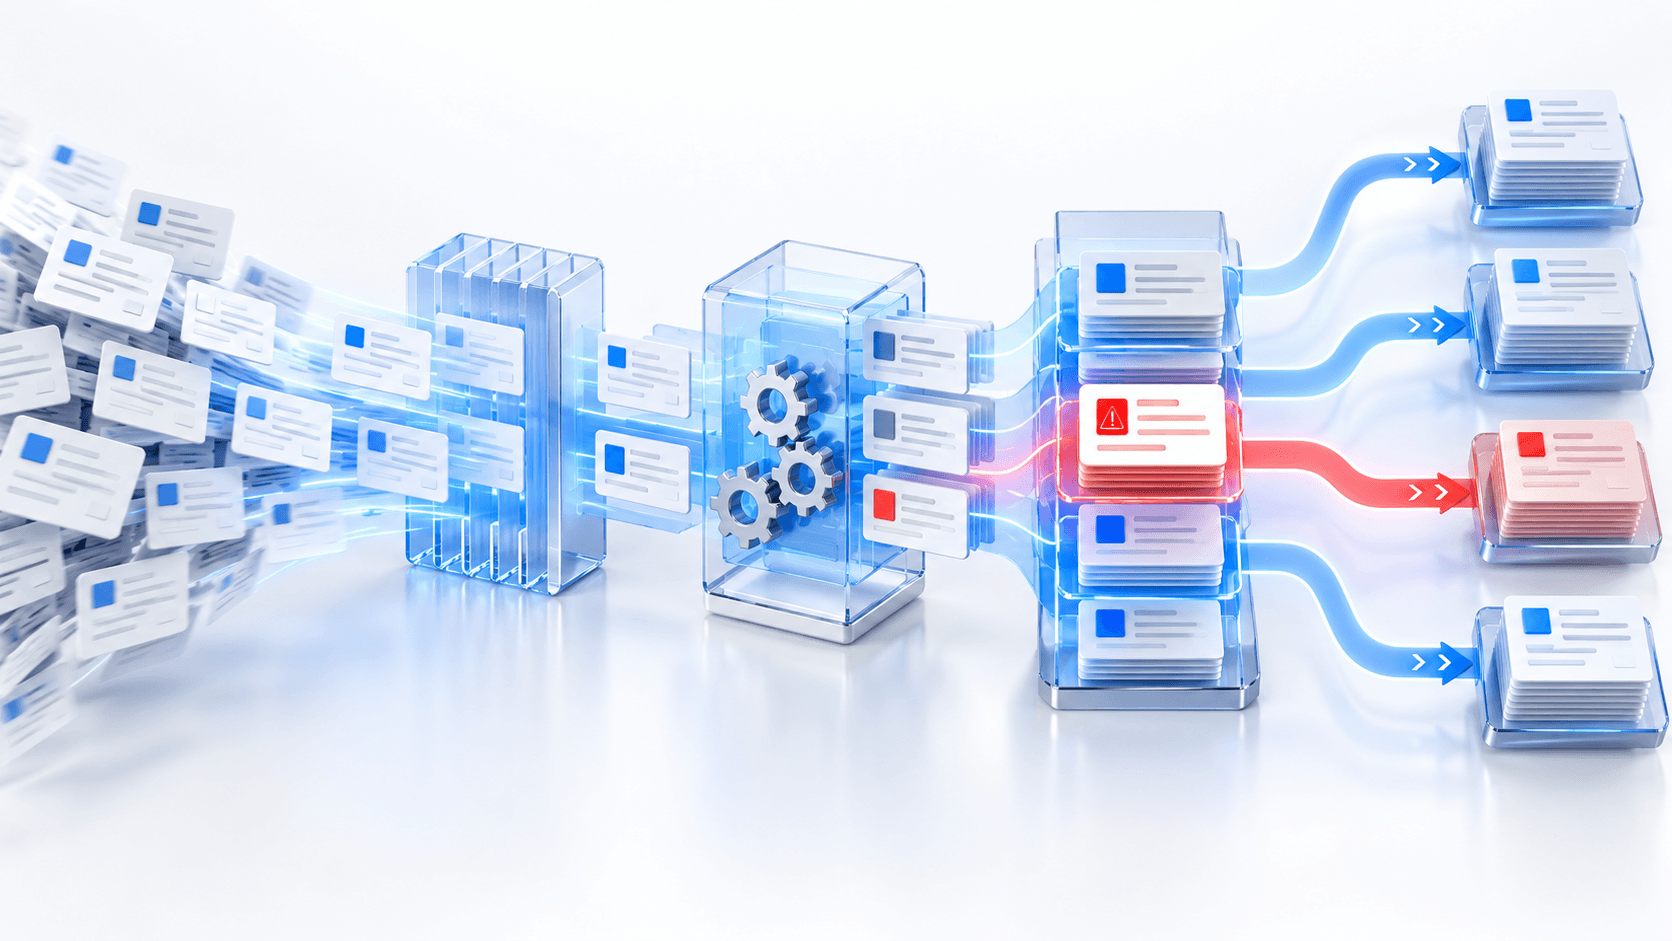
An AI agent can safely classify an IT ticket, collect missing context, identify likely duplicates, suggest urgency, and route the request before a specialist sees it. It should not make irreversible infrastructure changes, grant access, close uncertain incidents, or override security policy without an explicit rule and the right human approval.
The goal is a better handoff, not an autonomous help desk. When the agent prepares a consistent ticket and explains its recommendation, specialists spend less time sorting queues and more time resolving the issue. The same answer-first approach is useful in customer operations, as shown in this guide to AI in customer service.
Start with classification and enrichment
The safest first task is to turn an incomplete request into a usable work item. The agent can identify whether the ticket is an incident, service request, access request, problem, or change. It can extract the affected application, device, location, user, error message, and reported impact. If essential information is missing, it can ask a focused follow-up question before assigning the case.
Keep the original message alongside every extracted field. A specialist should be able to compare the agent’s interpretation with what the user actually wrote. If the agent is uncertain between two categories, it should record both possibilities and route to a general triage queue instead of forcing a confident label.
Atlassian documents how Jira Service Management uses request types and queues to organize work for triage. Its queue guidance is a useful reminder that classification should lead to a visible operational queue, not disappear inside the model.
Recommend urgency without inventing impact
An agent can compare the ticket with written priority rules. It may flag phrases that suggest an outage, security event, executive impact, or many affected users. It can also check approved sources such as monitoring alerts or the service catalog. The recommendation should show which evidence triggered the priority.
Do not let the model infer business impact from tone alone. A frustrated message may describe a minor issue, while a calm message may report a serious outage. High-impact or security-related tickets should move to an urgent human review path. AWS recommends matching human oversight to the consequence and reversibility of an action, with explicit approval for higher-risk decisions.

Route by service ownership and permissions
Routing should combine the predicted category with authoritative ownership data. The service catalog, configuration records, location, department, and support schedule can identify the correct team. The agent can propose an assignee, but the workflow should fall back to a controlled queue when ownership is missing or conflicting.
The agent only needs permission to read relevant context and update approved ticket fields. It does not need administrative access to the affected system. If a later workflow can reset a password or restart a service, treat that as a separate tool with its own authorization, policy checks, and approval rule.
Define the specialist handoff
A good handoff includes the original request, extracted facts, systems checked, duplicate candidates, suggested category, proposed priority, confidence notes, and unanswered questions. It should also show what the agent did not verify. This makes review faster and prevents the specialist from assuming that a recommendation is confirmed fact.
Consider a hypothetical employee who reports, “Finance system unavailable after login.” The agent checks the service catalog, asks whether colleagues are affected, and reads an approved monitoring alert. If only one user is affected and there is no outage signal, it routes the case to application support with the login error attached. If monitoring shows a regional outage, it raises the urgency and sends the ticket to incident management. It never restarts the production service on its own.
Measure whether triage is improving
Track routing precision, reassignment rate, time to specialist ownership, missing-field rate, duplicate suggestions accepted, and urgent cases that humans reclassified. Review mistakes by ticket type and source. A fast route to the wrong team is still poor service.
Run the agent in recommendation mode before allowing automatic field updates. Compare its decisions with experienced triage staff, then automate the stable categories first. Maintain a clear “unable to classify” outcome so uncertain cases remain visible.
Conclusion
AI is well suited to the preparation work before an IT specialist takes ownership: classification, enrichment, duplicate detection, evidence-based urgency, and routing. Safe deployment depends on narrow permissions, visible reasoning, and a reliable fallback queue. EXOPAI can help your team map the intake rules, service ownership, and approval boundaries needed for a controlled IT triage pilot.


